AICost.ai helps reduce AI costs and put governance controls in place across your enterprise
- Measure the real cost of every workflow step
- Cut cost without hurting quality
- Govern every workload inside your rules
We have mapped enterprise workflows, from RAG customer support to multimedia marketing and agentic AI in engineering, to AICost engines for the most savings and governance.

- Move AI from pilot to production with confidence
- Scale the workloads that pay off and stop the ones that don't
- Lower the operating cost of every AI workload
- Launch new AI-powered services faster
Example Enterprise Workflows and How AICost.ai Helps You
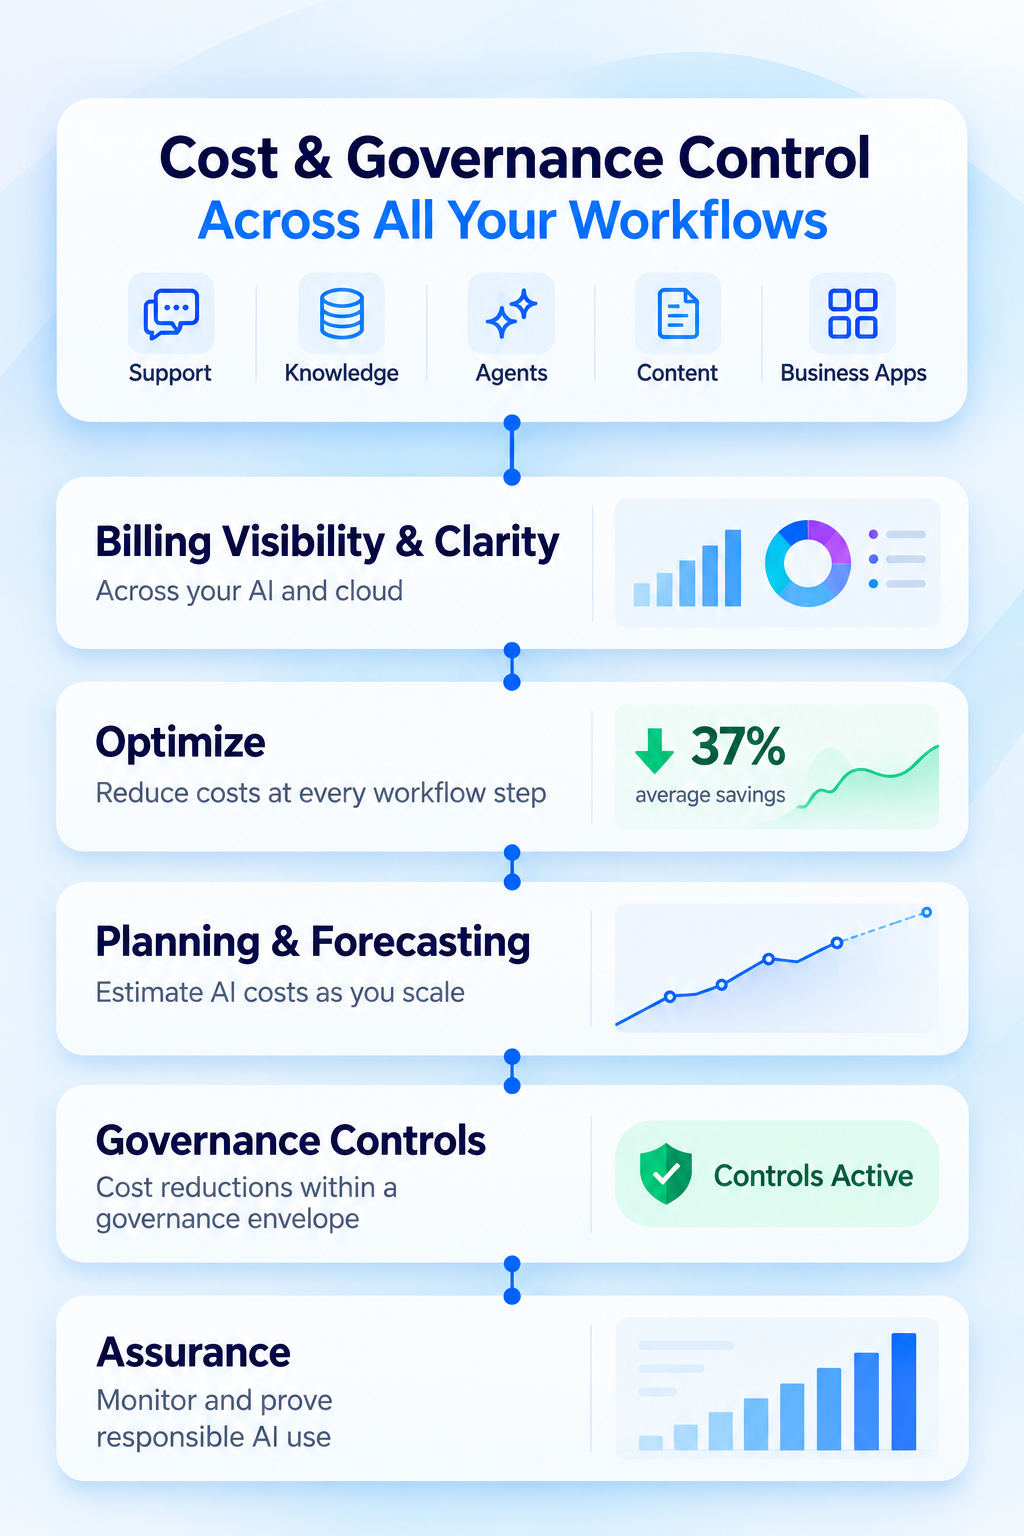
AICost.ai can cut cost across all your enterprise workflows.
124 engines. One job: keep AI cost and governance under control.
AICost measures what each workflow step costs, finds the best savings levers, and turns your policies into controls your AI follows.
Measure the real cost across workflows
AICost engines cover every part of your AI workflows, giving you visibility and the ability to optimize cost at every step.
- Request
- Knowledge (RAG)
- Agent
- Tools
- Retries
- Human review
Typical cost concentration by step. Every step is priced from one price database.
Best cost levers for the most cost reduction
AICost has 10 cost-lever engines and applies the right ones to each workflow step and AI use case for the most cost and governance benefit.
- Prompt cachingrepeat prompts
- Model routingeasy steps, cheaper model
- Batch processingwork that can wait
- Context compactionlong agent context
- Right-size modelspremium only where needed
Finds repeat prompts worth caching, by vendor
Sends each step to the cheapest capable model
Finds work that can wait for batch discounts
Trims long agent context and prices what you keep
Stacks caching, routing and batching correctly
Runs one workload across model families
Finds where open models on your GPUs pay off
Checks coding-assistant seats against output
Models the bill at 10x and 100x usage
Rolls up all cost layers into a go or no-go
Turn policy into continuous governance controls
AICost keeps your enterprise always governed: continuous governance runs as policies that work with your gateways or directly with AI vendor APIs.
- Budget limits
- Approved models
- Allowed tools
- Run limits
- Human approvals
- Audit evidence
Sets per-run ceilings, daily caps and a kill switch
Prices injection, PII and safety screening
Prices human approval on risky agent actions
Prices scoring a golden set on every release
Estimates yearly cost by EU AI Act risk tier
Scores data class against where a model comes from
Measures exposure to one AI vendor
Re-forecasts the year as agent use compounds
Projects month-end spend from month-to-date
Prices re-testing when vendors retire models
Featured engines
See all 124 engines →A few of the 124 deterministic cost and governance engines.
- Lower AI costDo more with the same budget
- Fewer surprise billsNo runaway spend
- Safer agentsGovernance and controls built in
- Confident scaleEconomics hold at production volume
The same engines work in every AI workflow you run: lower cost, with governance built in.
Accelerate business growth with AI, with cost and governance under control
AICost.ai's 124 decision engines cut AI cost inside your enterprise governance envelope.
- Where is our AI money really going?
- Why did costs spike last week?
Total visibility into AI and cloud cost across every enterprise workflow, step by step: cost per resolved case and the cause of every spike.
- How do we cut cost without hurting quality?
Every lever priced before you pull it: prompt caching, batching, model routing, loop caps and better grounding, all inside your quality floor.
50+ ready AI workflows, each with cost control built in- What will it cost when we scale?
- Will it pay back?
TCO, ROI and break-even at 1x, 10x and 100x, including human review, evaluation and the worst case, before you commit budget.
- What is this AI allowed to do?
- Who approved it?
Your rules become budgets, caps, model allowlists and human gates, enforced at the gateway you already run, with a versioned policy you approve.
20 assessment and governance modules, one approved policy- Is it ready for production?
- Will it still hold next month?
The workload you will ship is tested, gets a release decision, and is re-proven every day with evidence your auditor and board can read.
Assess it. Wall it. Protect it. Prove it.
Four steps to lower, governed AI cost
Every plan includes all four products. Pro is priced per workload and billed only when CostProof shows the savings.
CostAssess
See every AI workload, its cost and its gaps.
Best for: Enterprises, SIs and consultants
- Lite
- Price any workload: QuickStart, 54 workflows, designer
- Pro
- Read-only Microsoft 365 and Azure assessment, free
- Enterprise
- Estate review with our experts, 90-day plan
CostWall
Stop overspend in the gateway you already run.
Best for: Builders, AI-native companies, MSPs
- Lite
- Policy downloads for LiteLLM, Cloudflare and more
- Pro
- Caps per agent run, daily caps, kill switch
- Enterprise
- Runs in your own network
CostProtect
AI governance: keep every workload within your rules.
Best for: Enterprises, regulated teams, SIs
- Lite
- Control list for each workload
- Pro
- Approved models, data rules, assurance tests
- Enterprise
- Governance record and evidence for audits
CostProof
See the savings on your real bill.
Best for: AI-native companies, enterprises, MSPs
- Lite
- Estimate per step for any workload
- Pro
- Estimate vs actual from your gateway and cloud bill
- Enterprise
- Chargeback by team, audit export
Two clicks: who you are and what you need first.Find my products →
Cut AI cost with better governance, starting today
Talk to an AICost expert
See where AICost cuts cost and adds control on your own workloads.
Services for cost control and governance
Cost control and governance services for your business.
AICost.ai Complete Assessment
Know your whole AI estate in days, then set the right cost controls
Automated read-only collection plus a short interview, then a ranked plan of what to fix first.

AICost.ai Continuous Governance
Every cost rule becomes policy your gateway enforces, re-proven every day
The most cost-effective way to govern AI: priced on governed scope, never on your AI spend. Rules you approve run as executable policy, and the 124 engines re-check them as prices, models and usage change.
- Spend drift and spike alerts
- Price and model changes
- Weekly governance sweep
- Approvals with an evidence journal
- Assurance retests on every change
- AI inventory and shadow AI
- Regulatory exposure by workload
- Human review economics
- Detect
- Propose
- Approve
- Deploy
- ✓ Budgets and daily caps
- ✓ Cost per agent run
- ✓ Turn and retry limits
- ✓ Approved models by data class
- ✓ Human approval gates
- ✓ Emergency stop
- LiteLLM
- Portkey
- Kong
- Cloudflare AI Gateway
- AWS Bedrock
- Azure AI Foundry
- Google Vertex AI
- EU AI Act
- NIST AI RMF
- ISO 42001
- SOC 2
- your auditors and board
Start with one AI workload.
You do not need to replace your gateway. You do not need to replace your FinOps platform. You do not need to connect the entire enterprise.
Test us on one workload before you trust us with more.
Pick one workload. We will show you:
- what it really costs
- what happens at scale
- where the risks hide
- which controls it needs
- whether it is ready for production